The current landscape of generative media evaluation is largely dominated by “vibes.” When a new model drops, social media feeds are flooded with cherry-picked results—often a high-contrast portrait of a cyberpunk character or a hyper-realistic landscape—designed to trigger an immediate emotional response. For creative operations leads, these aesthetic peaks are essentially noise. A model’s ability to generate a single “golden frame” through exhaustive prompt engineering tells us nothing about its viability within a repeatable production pipeline.
The transition from experimental prompting to operational asset production requires a move away from generalist leaderboards. In a professional environment, the “best” model is rarely the one with the highest parameter count or the most aggressive marketing; it is the one that minimizes pipeline friction. This friction is a composite of inference economics, architectural consistency, and the reliability of sequential workflows. To build a robust pipeline, we must evaluate tools through a lens of operational stability rather than subjective visual appeal.
The Fallacy of the Generalist Leaderboard
Most public benchmarks for text-to-image models rely on Elo ratings or side-by-side human preference tests. While useful for general-purpose chat assistants, these metrics fail to account for the specific constraints of production. In a creative operations context, “preference” is secondary to “predictability.” If a model produces a stunning image 10% of the time but fails to maintain anatomical proportions or lighting consistency the other 90%, it is a liability, not an asset.
Furthermore, state-of-the-art (SOTA) models often carry hidden computational overhead. A model that requires 80GB of VRAM to generate a single 1024×1024 frame might win on a leaderboard, but it becomes a bottleneck when scaled to 10,000 assets for a dynamic ad campaign. We frequently see a disconnect between the performance reported in controlled research environments and the performance observed when these models are integrated into a multi-step design process.
For the operator, the question isn’t “Can it make a pretty picture?” but rather “Can it reproduce this specific visual logic 1,000 times without drifting into hallucinations?” Moving beyond the generalist leaderboard means defining custom benchmarks based on your team’s specific style guides and resolution requirements.
Quantifying Pipeline Friction: Latency and Latent Costs
Inference speed is often treated as a secondary metric, something to be optimized “later.” However, in a professional workflow, latency is a primary driver of cost. We must look at the “Inference-to-Iteration” ratio. If a high-fidelity model takes 45 seconds to generate an image, the feedback loop for a designer is effectively broken. A designer waiting nearly a minute for every variation will naturally produce fewer iterations, leading to a higher likelihood of settling for “good enough” rather than reaching the target quality.
There is a significant danger in over-specifying models for tasks that require high-volume, low-variability assets. For background elements, UI placeholders, or foundational textures, the ability to run multiple iterations quickly often outweighs the raw fidelity of a single high-latency render. This is where inference economics come into play. A model that is 20% less “detailed” but 400% faster allows for a more fluid creative process, which ultimately results in a better final product after human curation.
At this stage, we must admit a level of uncertainty: there is currently no industry-standard way to calculate the “cost of a discarded generation.” Until teams begin tracking the ratio of generated assets to used assets, the true economic impact of a model’s latency will remain speculative.
Architectural Integrity and the Sequential Workflow
Generative media tools are rarely used in isolation. A standard pipeline might involve initial generation, followed by inpainting to correct a specific detail, and finally a high-resolution upscale for print or 4K display. This sequential nature exposes the architectural weaknesses of many popular tools.
“Model drift” is a recurring issue during the upscaling phase. A common failure mode involves an upscaler introducing new, unintended textures—such as skin pores that look like orange peels or architectural details that no longer follow perspective—that were not present in the original low-res concept. If the upscaler invalidates a carefully approved initial concept, the entire workflow collapses.
Success should be measured by the percentage of output that requires zero human retouching between stages. If your team has to manually fix every “AI-enhanced” image in Photoshop, the tool has failed its primary purpose of operational efficiency. A robust architecture prioritizes the preservation of global structure over the addition of micro-detail that doesn’t belong.
The Case for Optimized Inference: Kimg AI in Practice
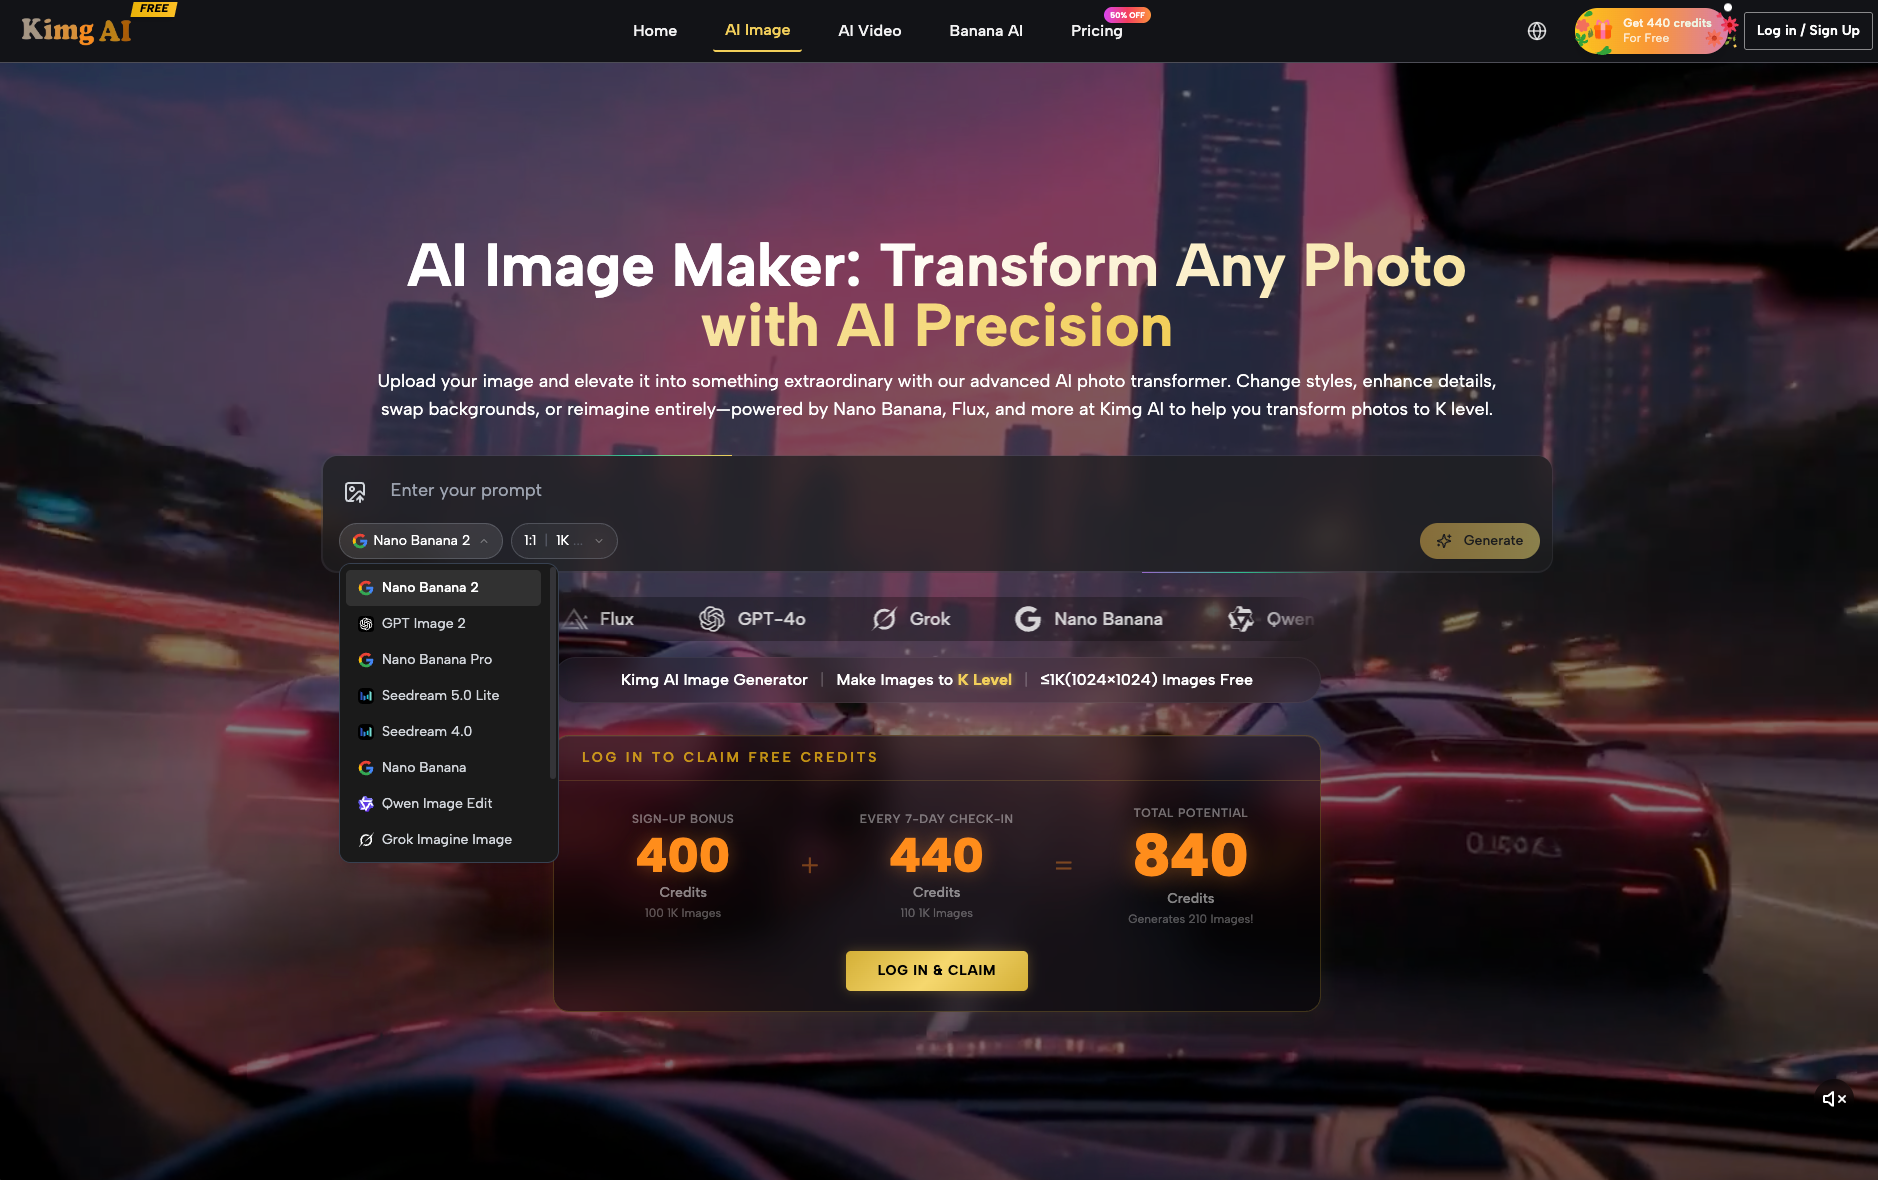
When evaluating tools for scale, it becomes necessary to look at specialized model architectures that prioritize throughput. For example, Nano Banana AI serves as a case study for balancing resolution with operational speed. Within the Kimg AI ecosystem, this model is designed to handle high-resolution upscaling and generation tasks without the heavy computational bloat associated with generalist “mega-models.”
By utilizing a more lightweight framework, Nano Banana allows for rapid prototyping. In a scenario where an agency needs to generate 500 variations of a product background, using a massive, high-parameter model would be cost-prohibitive and slow. The specialized nature of Nano Banana AI suggests a shift toward “fit-for-purpose” models—tools that are optimized for specific tasks like K-level resolution or style-consistent inpainting rather than trying to be everything to everyone.
It is also worth noting how Banana AI fits into the broader selection of models like Flux or Grok. While the latter might excel in raw prompt adherence for complex, multi-subject scenes, the former often proves more efficient for the repetitive, resolution-critical tasks that make up the bulk of a creative team’s daily workload. This highlights the importance of choosing the right tool for the specific stage of the pipeline rather than defaulting to the most famous model available.
The Transparency Gap: What We Cannot Safely Conclude
Despite the rapid progress in the field, there are several areas where cautious skepticism is mandatory. First, we lack long-term data on “style drift” within enterprise environments. When models are fine-tuned across different datasets or used in conjunction with various LoRAs (Low-Rank Adaptations), the long-term stability of the model’s “creative DNA” is unknown. Will the model’s outputs begin to degrade or homogenize after months of heavy use? We don’t know yet.
Second, the legal and copyright landscape remains volatile. While many platforms claim their models are trained on licensed data, the actual transparency of training sets is often opaque. For a creative operations lead, this represents a significant risk factor that no benchmark can currently quantify. We must operate under the assumption that the legal status of any generative asset is subject to change.
Finally, “operational fit” is a moving target. As hardware optimization techniques like quantization and pruning evolve, a model that is currently too slow for production might become viable in six months. Conversely, a tool that seems efficient today might become obsolete as new, more streamlined architectures emerge.
Building a generative media pipeline is not about chasing the latest trend. It is about establishing a rigorous, evidence-first framework that prioritizes the economic realities of scale and the technical requirements of a sequential workflow. By focusing on latency, architectural consistency, and inference economics, creative teams can move past the hype and build systems that actually deliver value.
